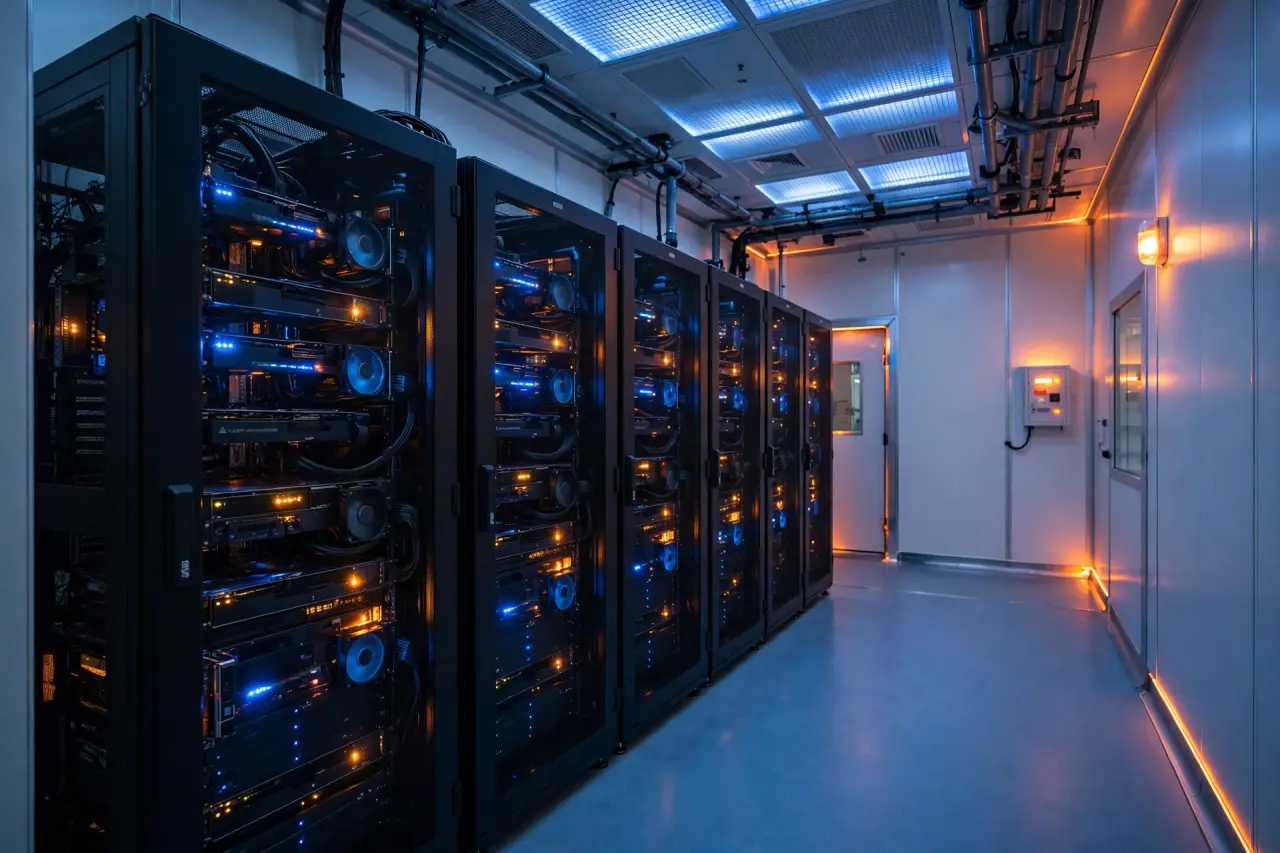
The mirror is live. That is the whole point of this post. We operate a mirrored pair of sites, with the second site 20 to 50 miles from the first, carrying live traffic in a serial path to end users. It is not a plan, not a slide, and not a standby site that has never run. It is operating, and operating it is what teaches you the difference between high availability and a promise.
Start with the terms, because they are used loosely and the difference matters. High availability means a system or application is configured to be available at least 99.99 percent of the time, which is about 52.6 minutes of unavailability in a year. Our pair sits at 20 to 50 miles. We call that Metro High Availability, not disaster recovery. By disaster recovery we mean a second site in a different region, far enough away that one regional event cannot take out both. We use 100 miles as our own working threshold; published sources describe that distance only loosely. In our naming, the distance decides the category. Ours is metro, and we call it what it is.
The second distinction is what the second site does on a normal day. In active-passive failover, one active component handles all tasks while a passive component remains on standby, ready to take over if the active component fails. In active-active failover, multiple active components share the load and work simultaneously, and if one fails the others continue and traffic is rerouted to the remaining servers. Our mirror runs in a serial path to end users. It carries live traffic. It is not a cold standby, and it is not a recovery target that sits idle. That is the difference between a site you have tested and a site you hope works.
Replication is where the operational work lives. Recovery time objective is the period within which protected systems must be restored to full operating service, and recovery point objective is the amount of data, expressed in terms of time, that can acceptably be lost. In synchronous replication, a write is confirmed only after both the primary and secondary systems have stored it, which produces zero or near zero data loss but makes every write wait on the remote site. In asynchronous replication, the primary confirms the write right away and sends changes afterward, so applications stay fast and sites can be far apart, but the secondary may lag by seconds or minutes and that lag is the data that could be lost. Synchronous replication usually works best between sites that are close together because distance and network latency directly affect application speed. The choice is a tradeoff, and the tradeoff is distance. At 20 to 50 miles, synchronous replication is practical. That is one reason the metro pair works. We do not publish a recovery time or recovery point number for our pair, because a number without a tested failover behind it is a guess. The definitions above are the terms. Our numbers will come from tests, not from a brochure.
Testing is the lesson the live pair teaches most clearly. An untested plan is a guess, and failover exercises should be run regularly, with each step timed and compared with the recovery time objective, because tests usually turn up small problems such as an expired credential or an unreplicated configuration file. Application dependencies must be mapped first, and the whole chain replicated with the start order documented, or failover will stall on a missing piece. Clear runbooks must define when to rely on high availability versus when to initiate disaster recovery, and regular non-disruptive testing should check boot order, application dependencies, network mappings, and procedures.
The commercial term follows the same logic. We mirror a workload at a second site 20 to 50 miles from the first at 25 percent off the second site for the first 36 months, then full price. Compare that with the only published second-site discount we found. Flex Data Center’s website lists colocation at up to 50 percent off standard rates for disaster recovery, by requiring a commitment to only 50 percent of installed power, for customers with power efficient disaster recovery strategies who require more than 50 kW of installed power at peak. The reasoning on that page is that secondary or failover data centers are usually not fully utilized, yet most data centers charge full price for disaster recovery colocation. As disaster recovery, 25 percent looks weak against 50 percent. As high availability, where the second site is live and carrying traffic, we know of no published discount at all, so we think 25 percent off is a fair offer. That is the distinction, and it is why we call the product Metro High Availability and not disaster recovery. You are not paying for a site that sits idle. You are paying for a site that runs.
A live asset beats a claim. That is the point of the mirror, and it is the point of this post. We operate the pair. We test it. We offer it wherever we build. We will publish our measured failover results when we have them, with the method and the date attached, the same way we will publish our measured latency. Until then, the fact that matters is the one we can state plainly: the mirror is live, it carries traffic in a serial path to end users, and it is not just backup or standby.
Sources
- Disaster Recovery Journal, How to Find the Right Balance Between Cost and Level of System and Application Availability: https://drj.com/journal_main/how-to-find-the-right-balance-between-cost-and-level-of-system-and-application-availability/
- VM Infrastructure, The Best of Both Worlds: Combining VMware Stretched Clusters with Live Site Recovery for Long-Distance Resilience: https://vminfrastructure.com/2026/05/22/the-best-of-both-worlds-combining-vmware-stretched-clusters-with-live-site-recovery-for-long-distance-resilience/
- GeeksforGeeks, Failover Patterns in System Design: https://www.geeksforgeeks.org/system-design/failover-patterns-system-design/
- Volico, Disaster Recovery Replication: https://www.volico.com/disaster-recovery-replication/
- Dell, Business Continuity and Disaster Recovery with Dell PowerMax Storage: https://www.dell.com/en-us/infohub/articles/business-continuity-and-disaster-recovery-with-dell-powermax-storage-for-sap-hana-tdi-deployments-1
- Flex Data Center, Disaster Recovery Colocation (undated page, viewed November 2026): https://www.flexdata.center/disaster-recovery